
Platform / Integrations
Connect the stack you have. Keep the freedom to change it.
LyftData sits between the systems producing your data and the platforms that consume it, so collection, transformation, routing and policy don't have to belong to one downstream vendor.
Sources
- Object storage
- Security & endpoint
- OS & event logs
- SaaS & analytics exports
- HTTP & APIs
LYFTDATA
The independent control layer
- Collect
- Transform
- Route
- Govern
- Observe
Collect once, govern centrally, route where the data should go.
Destinations
- SIEM
- Observability
- Storage & archive
- Analytics & warehouse
Why it matters
A destination should consume your data. It shouldn't own the path to it.
When collection, transformation and routing live inside one downstream platform, switching or adding a tool means rebuilding pipelines. Keep those upstream and the destination becomes a routing decision.
Connect the systems you use today. Keep the freedom to replace the ones you don't.
The integration model
Every connection is the same four steps.
LyftData connects through inputs and outputs. Some are purpose-built for a system; others use a shared mechanism — HTTP delivery, object storage, or API polling — documented per system.
Inputs
read from a source — some purpose-built (object storage, Windows Event Log), others over HTTP or polling.
Actions
filter, parse, normalize, mask and enrich in the layer you control, before anything leaves it.
Channels
clone a governed stream so one source can feed several destinations in parallel.
Outputs
deliver to a destination — a dedicated output, or a shared one like HEC-style HTTP or object storage.
Each catalog entry links to its product-integration guide. Some guides are complete; others are marked in progress. Where support level matters for your evaluation, the guide is the source of truth.
Catalog
Find the system you're working with.
The systems with a published or in-progress product-integration guide today. Search by name or capability, or filter by category. Logos are technology references, not partnerships.
13 of 13 shown
 Amazon S3
Configure jobs that read from or write to S3-compatible object storage using the documented modes.
SourceDestinationCloudStorageOpen guide → Microsoft Azure
LyftData supports reading from and writing to Azure Blob Storage via the azure-blob connectors.
SourceDestinationCloudSecurityOpen guide → CrowdStrike
Use the splunk-hec or http-post outputs to send events to CrowdStrike Falcon LogScale endpoints.
DestinationSecurityOpen guide → CDM
The CDM guide covers polling Detection Monitoring APIs with http-poll while docs are finalized.
SourceSecurityOpen guide → Google Cloud Storage
LyftData ships first-class support for reading from and writing to Google Cloud Storage.
SourceDestinationCloudStorageOpen guide → Splunk
Use the Splunk HEC output to deliver events to Splunk Cloud or Splunk Enterprise.
DestinationObservabilitySecurityOpen guide → Microsoft Sentinel
Docs note support for reading from and writing to Microsoft Sentinel while the full guide is in progress.
SourceDestinationSecuritySIEMOpen guide → Logsign
Write data to Logsign using the documented http-post or file outputs (guide in progress).
DestinationSecurityOpen guide → Segment
Ingest Segment exports from S3, Azure Blob, GCS, or the Segment delivery APIs.
SourceCustomer DataAnalyticsOpen guide → Google Analytics 4
Import GA4 exports mirrored to GCS or S3 using the gcs or s3 inputs and preprocessors.
SourceAnalyticsMarketingOpen guide → Google Ads Manager
Collect Google Ad Manager report exports from GCS or S3 using documented regex and preprocessing options.
SourceMarketingAnalyticsOpen guide → Windows
Read Windows Event Log data with the windows-event-log input (guide in progress).
SourceOSSecurityOpen guide → Scuba
Read from and write to Scuba Analytics via object storage or HTTP delivery connectors (guide in progress).
SourceDestinationAnalyticsOpen guide →
Beyond named systems
The catalog is a starting point, not the boundary.
Inputs, actions and outputs are composable primitives — a source or destination doesn't need a named catalog entry to be reachable over the mechanisms LyftData already supports.
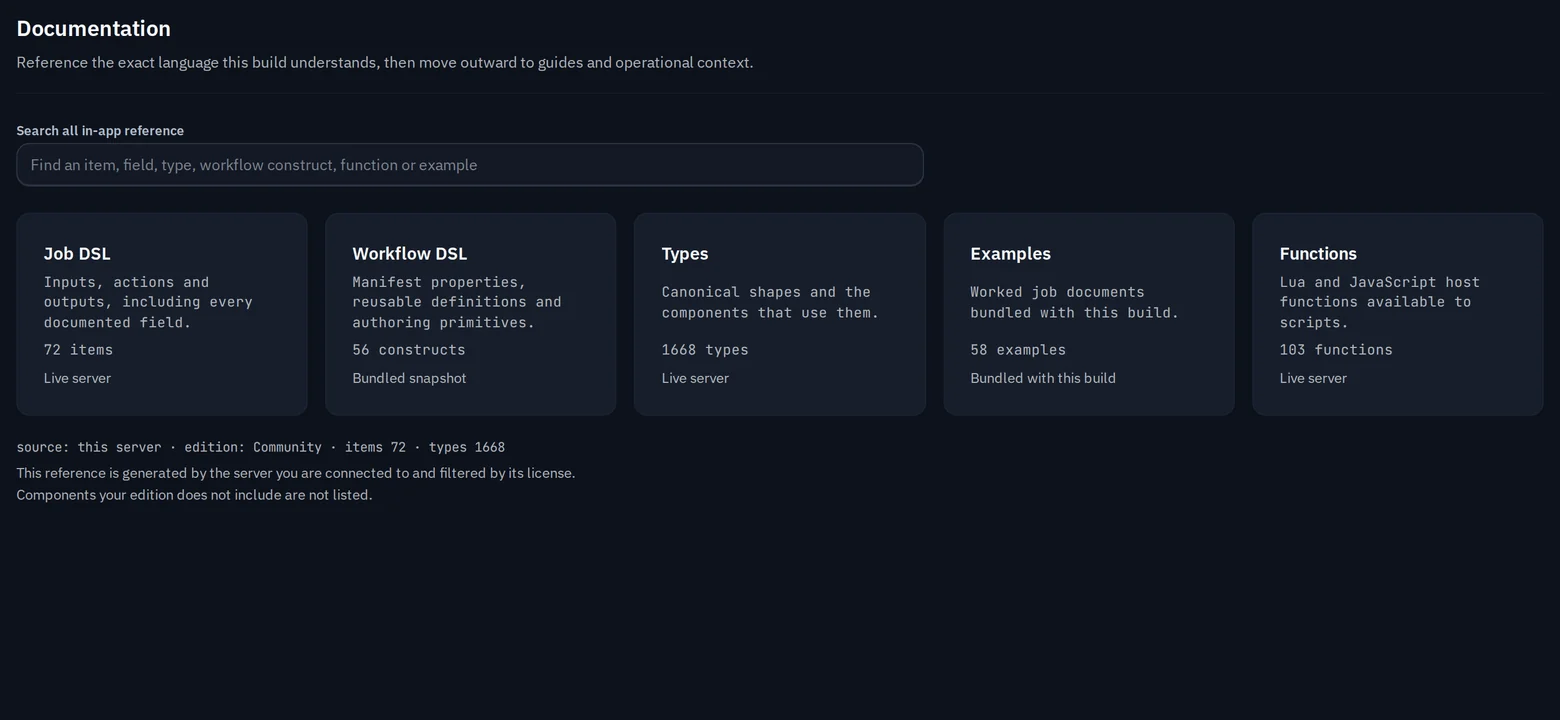
One source does not have to mean one destination. Collect it once and route governed copies to every system that needs it.
Missing something?
Tell us what you need to connect.
Let us know the system and whether you're collecting from it, delivering to it, or both.
Request an integrationConnect the stack. Keep the data layer independent.
Start with LyftData, or walk through your sources and destinations with the team.